import matplotlib.pyplot as plt
import seaborn as sns
import yfinance as yf

sns.set_theme()Downloading Financial Data
The Package yfinance
We’ll use the yfinance package to download stock price data from Yahoo! Finance. This Python library provides a simple interface for retrieving historical market data for stocks, indices, and other financial instruments. Before using it, you’ll need to install it first.
Anaconda
If you are using Anaconda you need to install yfinance first before you use it for the first time. In an Anaconda command prompt type:
pip install yfinance --upgradeor in a Jupyter cell you can type:
!pip install yfinance --upgrade --quietGoogle Colab
In Google Colab, yfinance is pre-installed. If you ever need to upgrade to the latest version run this in a code cell:
!pip install yfinance --upgrade --quietImporting the Libraries
You can import the libraries as follows.
Data
In order to estimate asset pricing models, we need to get data on stock returns, for both a particular security and the market. An easy way to do the is to download this data from the web. We start by defining the security that we want to analyze and from which date we want to start the analysis.
To get the data, we use the function download() in yfinance. For example, to get the data for Microsoft (ticker: MSFT) we type:
yf.download(tickers='MSFT', auto_adjust=False, progress=False, multi_level_index=False)| Adj Close | Close | High | Low | Open | Volume | |
|---|---|---|---|---|---|---|
| Date | ||||||
| 2026-09-14 | 505.410004 | 505.410004 | 509.950012 | 495.339996 | 497.059998 | 23091900 |
| 2026-09-15 | 497.119995 | 497.119995 | 505.899994 | 495.540009 | 500.059998 | 17794600 |
| 2026-09-16 | 490.299988 | 490.299988 | 495.970001 | 487.230011 | 493.029999 | 16670300 |
| 2026-09-17 | 497.750000 | 497.750000 | 501.470001 | 493.170013 | 497.799988 | 17841600 |
| 2026-09-18 | 493.779999 | 493.779999 | 498.649994 | 491.100006 | 497.970001 | 39622300 |
| 2026-09-21 | 501.609985 | 501.609985 | 501.869995 | 491.329987 | 494.950012 | 27959900 |
| 2026-09-22 | 498.000000 | 498.000000 | 508.500000 | 493.649994 | 507.320007 | 21652800 |
| 2026-09-23 | 500.589996 | 500.589996 | 509.440002 | 495.880005 | 500.760010 | 19445600 |
| 2026-09-24 | 497.929993 | 497.929993 | 498.899994 | 491.220001 | 495.070007 | 16657600 |
| 2026-09-25 | 516.169983 | 516.169983 | 519.400024 | 497.250000 | 499.040009 | 38193100 |
| 2026-09-28 | 509.220001 | 509.220001 | 513.330017 | 502.220001 | 505.470001 | 19626900 |
| 2026-09-29 | 508.959991 | 508.959991 | 513.640015 | 502.399994 | 508.309998 | 21341800 |
| 2026-09-30 | 512.900024 | 512.900024 | 519.830017 | 510.309998 | 511.609985 | 27223300 |
| 2026-10-01 | 512.799988 | 512.799988 | 522.849976 | 512.169983 | 519.880005 | 19731900 |
| 2026-10-02 | 517.530029 | 517.530029 | 522.500000 | 513.659973 | 519.390015 | 17822300 |
| 2026-10-05 | 525.179993 | 525.179993 | 532.349976 | 521.469971 | 521.619995 | 26604800 |
| 2026-10-06 | 529.299988 | 529.299988 | 535.690002 | 528.780029 | 531.679993 | 21107500 |
| 2026-10-07 | 529.760010 | 529.760010 | 531.729980 | 524.690002 | 530.729980 | 16790200 |
| 2026-10-08 | 522.609985 | 522.609985 | 533.510010 | 518.789978 | 529.809998 | 20228700 |
| 2026-10-09 | 535.070007 | 535.070007 | 537.219971 | 526.239990 | 528.239990 | 18500600 |
| 2026-10-12 | 541.150024 | 541.150024 | 542.739990 | 535.700012 | 537.530029 | 18314900 |
| 2026-10-13 | 543.450012 | 543.450012 | 551.150024 | 543.059998 | 544.640015 | 23824500 |
The output of the function download() is a Pandas dataframe. Therefore, all operations available on Pandas work on the dataframe just imported.
The yfinance library was recently updated so that the Close column now shows split and dividend-adjusted prices by default. To get both the unadjusted price and the adjusted price separately, we need to set auto_adjust=False when downloading data.
I use the option progress=False to suppress the status bar when downloading the data. The code runs just as fine without it.
The option multi_level_index=False flattens the column names to a single level. Without it, yfinance returns columns with two levels (price type and ticker), so you would need to write df['Close']['MSFT'] instead of simply df['Close'].
Also, note that by default, the dataset only includes data for the last month. We can specify an arbitrary starting date by adding, for example, start='2012-01-01'.
yf.download(tickers='MSFT', start='2012-01-01', auto_adjust=False, progress=False, multi_level_index=False)| Adj Close | Close | High | Low | Open | Volume | |
|---|---|---|---|---|---|---|
| Date | ||||||
| 2012-01-03 | 20.833267 | 26.770000 | 26.959999 | 26.389999 | 26.549999 | 64731500 |
| 2012-01-04 | 21.323555 | 27.400000 | 27.469999 | 26.780001 | 26.820000 | 80516100 |
| 2012-01-05 | 21.541464 | 27.680000 | 27.730000 | 27.290001 | 27.379999 | 56081400 |
| 2012-01-06 | 21.876099 | 28.110001 | 28.190001 | 27.530001 | 27.530001 | 99455500 |
| 2012-01-09 | 21.588152 | 27.740000 | 28.100000 | 27.719999 | 28.049999 | 59706800 |
| ... | ... | ... | ... | ... | ... | ... |
| 2026-10-07 | 529.760010 | 529.760010 | 531.729980 | 524.690002 | 530.729980 | 16790200 |
| 2026-10-08 | 522.609985 | 522.609985 | 533.510010 | 518.789978 | 529.809998 | 20228700 |
| 2026-10-09 | 535.070007 | 535.070007 | 537.219971 | 526.239990 | 528.239990 | 18500600 |
| 2026-10-12 | 541.150024 | 541.150024 | 542.739990 | 535.700012 | 537.530029 | 18314900 |
| 2026-10-13 | 543.450012 | 543.450012 | 551.150024 | 543.059998 | 544.640015 | 23824500 |
3716 rows × 6 columns
Close v/s Adjusted Close Price
The data query produces six columns. When estimating asset pricing models we will be interested in using the adjusted close (Adj Close) column since the price series is adjusted for stock splits and dividends. Let’s compare how the Adj Close differs from the Close price.
For this, let’s extract these two series and store them in a dataframe called df. The method df.loc[:, [column_label_1, column_label_2, ..., column_label_n]] selects multiple columns from the dataframe. In our example we want to select loc[:, ['Close', 'Adj Close']].
df = yf.download(tickers='MSFT', start='2012-01-01', auto_adjust=False, progress=False, multi_level_index=False).loc[:, ['Close', 'Adj Close']]Sometimes in Python lines might get really long. A suggested way to split a long line of code into several smaller lines is to use parentheses around the code that you want to split and split whenever there is a dot.
df = (yf
      .download(tickers='MSFT', start='2012-01-01', auto_adjust=False, progress=False, multi_level_index=False)
      .loc[:, ['Close', 'Adj Close']]
      )
The previous line of code does exactly the same as the one we wrote originally, but might be easier to read and understand.
We can now compute cumulative percentage changes (cum_pct) for both series by applying to each column in df a function that divides everything by the first price. The apply() method applies a function along an axis of a DataFrame or a Series. The function can be a built-in Python function or a custom function that you define.
First, we define a function that takes a series x as input and divides the series by its initial value x[0].1
1 In the original code, I wrote x / x[0]. However, that syntax is being deprecated and the suggestion is to access the row number of the pandas dataframe using iloc.
def normalize(x):
    return x / x.iloc[0]
Then, we apply this function to our dataframe and plot it.
cum_pct = df.apply(normalize)
cum_pct.plot()
plt.title('Close v/s Adjusted Close of Microsoft')
plt.ylabel('Cumulative Return')
plt.show()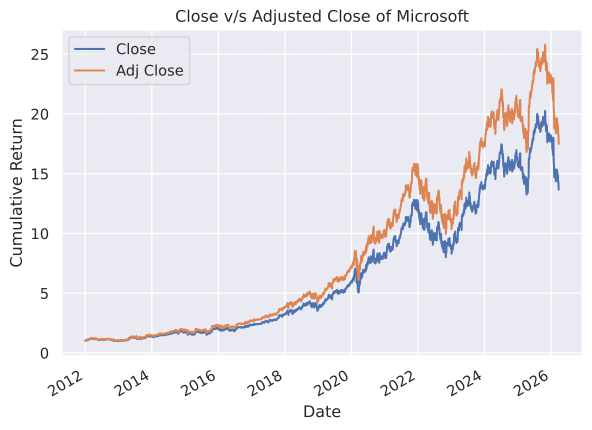
According to the graph, the impact of dividends is significant. Another way to see this is by actually computing the dividends from the two series. We will do this later.
Practice Problems
Problem 1 Plot the Close price for Nvidia Corporation (Ticker: NVDA) from July 1, 2015 until May 1, 2023.
Solution
df = yf.download(tickers='NVDA', start='2015-07-01', end='2023-05-01', auto_adjust=False, progress=False, multi_level_index=False).loc[:,['Close']]
df.plot()
plt.title('NVDA Stock Price')
plt.show()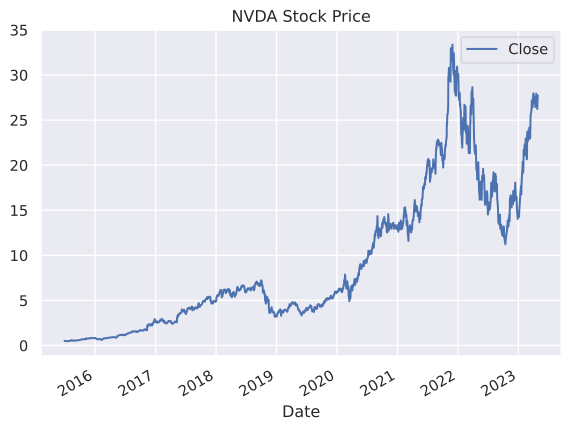
Problem 2 Plot the S&P 500 (Ticker: ^GSPC) from January 1, 2018 until May 1, 2023. Since the S&P 500 is an index you can use either the Close or Adj Close, it does not make a difference.
Solution
df = yf.download(tickers='^GSPC', start='2018-01-01', end='2023-05-01', auto_adjust=False, progress=False, multi_level_index=False).loc[:,['Close']]
df.plot()
plt.title('S&P 500')
plt.show()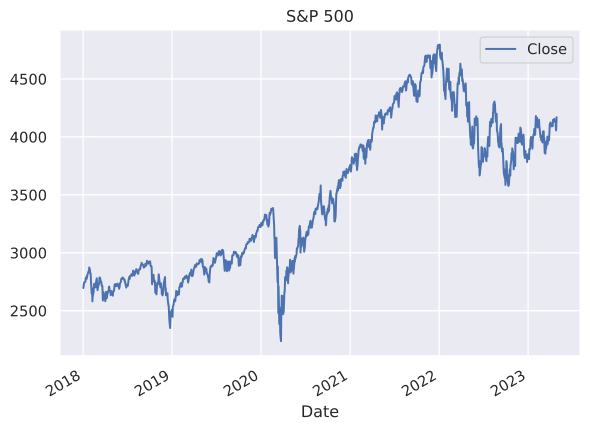
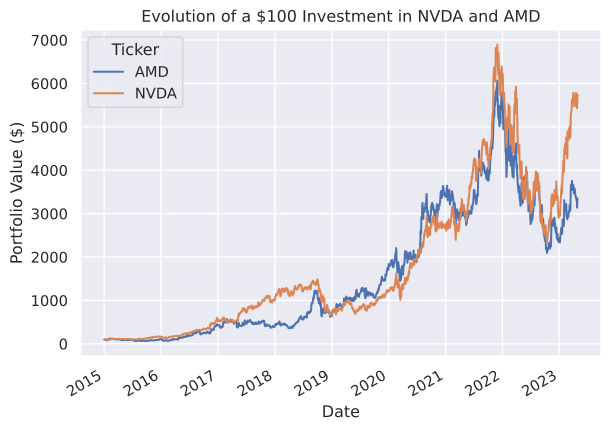
Problem 3 Imagine that you invest $100 in NVDA and AMD in January 1, 2015. Plot the evolution of each investment until May 1, 2023.
Solution
To plot the evolution of each investment, all we need to do is normalize the Adj Close evolution to 100 in January 1, 2015 for both stocks. We can use the same function we built before and multiply the result by 100. We use Adj Close instead of Close to account for stock splits and dividends.
df = (yf
      .download(tickers=['NVDA', 'AMD'], start='2015-01-01', end='2023-05-01', auto_adjust=False, progress=False)
      .loc[:, 'Adj Close']
      .apply(normalize)
      )*100
df.plot()
plt.title('Evolution of a $100 Investment in NVDA and AMD')
plt.ylabel('Portfolio Value ($)')
plt.show()