import io
import os
from contextlib import redirect_stdout
from pathlib import Path

import matplotlib as mpl
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
from scipy.optimize import minimize
from scipy.special import gammainc, gammaincc, gammaln

# Make SVG figures byte-identical across reruns, so the frozen outputs
# change in git only when a figure does
os.environ.setdefault("SOURCE_DATE_EPOCH", "0")
mpl.rcParams["svg.hashsalt"] = "waiting-for-the-second-trade"

DATA_DIR = Path("../_data")


def load_wrds(name, sql):
    file = DATA_DIR / f"{name}.parquet"
    if not file.exists():
        import wrds
        with redirect_stdout(io.StringIO()):
            conn = wrds.Connection()
            df = conn.raw_sql(sql)
            conn.close()
        DATA_DIR.mkdir(exist_ok=True)
        df.to_parquet(file)
return pd.read_parquet(file)Waiting for the Second Trade
Introduction
If trades in a bond arrive as a Poisson process with rate \lambda, the times between trades are independent exponential random variables, and the waiting time W until the second trade, the sum of two of them, has a \text{Gamma}(2, \lambda) distribution. This notebook takes the gamma model to one day of corporate bond transactions from Enhanced TRACE. We keep \alpha and \lambda the same for every bond, but we estimate the shape \alpha instead of fixing it at 2, so the estimate tells us how far the data are from the Poisson benchmark.
The density of a \text{Gamma}(\alpha, \lambda) random variable is f(w) = \frac{\lambda^\alpha}{\Gamma(\alpha)} w^{\alpha - 1} e^{-\lambda w}, \qquad w > 0, \tag{1} with mean \operatorname{E}(W) = \alpha / \lambda and variance \alpha / \lambda^2.
Data
We use all trades executed on Wednesday, October 15, 2025. The sample consists of corporate bonds with at least one customer trade in the month before that day, which keeps out the thousands of bonds outstanding that almost never trade. Bonds in the sample that do not trade on October 15 stay in, because they tell us how long the wait can be.
day = load_wrds("trace_2025-10-15", """
    SELECT cusip_id, trd_exctn_tm, trc_st, msg_seq_nb, orig_msg_seq_nb,
           entrd_vol_qt, rptd_pr, rpt_side_cd, cntra_mp_id, sub_prdct, wis_fl
    FROM trace_enhanced.trace_enhanced
    WHERE trd_exctn_dt = '2025-10-15'
""")

universe = load_wrds("trace_universe_2025-10-15", """
    SELECT DISTINCT cusip_id
    FROM trace_enhanced.trace_enhanced
    WHERE trd_exctn_dt BETWEEN '2025-09-15' AND '2025-10-14'
      AND cntra_mp_id = 'C'
      AND trc_st = 'T'
      AND sub_prdct = 'CORP'
""")
TRACE records errors as separate rows that point back to the original trade report. We follow the filter of Dick-Nielsen (2014) for data reported after February 2012. A cancellation (X) or correction (C) repeats the original report with the same message sequence number, and both the original and the cancellation or correction are deleted. A correction also files a replacement report (R) with the correct terms, which stays in the data. A reversal (Y) points to the original through orig_msg_seq_nb, and both are deleted. Besides the sequence number, a report is matched to the original on CUSIP, volume, price, execution time, side and counterparty.
Dick-Nielsen, Jens. 2014. How to Clean Enhanced TRACE Data. Working Paper. Copenhagen Business School.
We then keep customer trades only (cntra_mp_id = 'C'). A trade between two dealers is reported by both, and a dealer who buys from a customer often sells to another dealer seconds later, so counting interdealer trades would produce many artificially short waits. Time is measured in hours from 8:00 a.m. Eastern, and the day ends at 5:00 p.m., nine hours later.
match = ["cusip_id", "entrd_vol_qt", "rptd_pr", "trd_exctn_tm", "rpt_side_cd",
         "cntra_mp_id", "msg_seq_nb"]
cancelled = day[day.trc_st.isin(["X", "C"])]
reversed_ = day[day.trc_st == "Y"].drop(columns="msg_seq_nb").rename(
    columns={"orig_msg_seq_nb": "msg_seq_nb"})
dead = pd.concat([cancelled[match], reversed_[match]]).drop_duplicates()

trades = day[day.trc_st.isin(["T", "R"])].merge(dead, on=match, how="left", indicator=True)
trades = trades[trades._merge == "left_only"].drop(columns="_merge")

trades = trades[
    (trades.cntra_mp_id == "C")
    & (trades.sub_prdct == "CORP")
    & (trades.wis_fl != "Y")
    & trades.cusip_id.isin(universe.cusip_id)
]

hours = pd.to_timedelta(trades.trd_exctn_tm.astype(str)).dt.total_seconds() / 3600 - 8
trades = trades.assign(t=hours)[(hours > 0) & (hours <= 9)]

counts = trades.groupby("cusip_id").size().reindex(universe.cusip_id, fill_value=0)
print(f"Bonds in the sample:          {len(counts):,}")
print(f"Customer trades on the day:   {counts.sum():,}")
print(f"Bonds with no trade:          {(counts == 0).mean():.1%}")
print(f"Bonds with two or more:       {(counts >= 2).mean():.1%}")
Bonds in the sample: 31,603
Customer trades on the day: 69,085
Bonds with no trade: 65.7%
Bonds with two or more: 25.4%For each bond that trades at least twice, the waiting time w_i is the time of its second customer trade.
w = trades.sort_values("t").groupby("cusip_id").t.nth(1).to_numpy()
n_bonds = len(counts)
Maximum likelihood with censoring
We observe each bond until some time T. A bond whose second trade happens at w_i \leq T contributes the density (1) to the likelihood. A bond that has not traded twice by T contributes the probability of that event, \operatorname{P}(W > T) = 1 - F(T). Writing n_c for the number of censored bonds, the log-likelihood is \ell(\alpha, \lambda) = \sum_{w_i \leq T} \Big( \alpha \ln \lambda - \ln \Gamma(\alpha) + (\alpha - 1) \ln w_i - \lambda w_i \Big) + n_c \ln Q(\alpha, \lambda T), \tag{2} where Q(\alpha, x) = \Gamma(\alpha, x) / \Gamma(\alpha) is the regularized upper incomplete gamma function, so that 1 - F(T) = Q(\alpha, \lambda T). Dropping the censored bonds would keep only the bonds that trade often and bias \lambda upward. Because every bond is observed over the same window, the censoring term is the only adjustment needed.
Later we let the rate change during the day. The code is written for that case from the start, using the expected number of trades by time t, \Lambda(t) = \int_0^t \lambda(s) \, ds, which equals \lambda t when the rate is constant. We take \lambda(t) to be constant between break points, so a single break at \tau gives \Lambda(t) = \lambda_1 \min(t, \tau) + \lambda_2 \max(t - \tau, 0). We maximize over \ln \alpha and the log rates to keep all parameters positive, and compute standard errors from a numerical Hessian of the log-likelihood.
def clock(t, rates, breaks):
    edges = np.concatenate([[0.0], breaks, [np.inf]])
    widths = np.diff(edges)
    return sum(r * np.clip(t - e, 0, d) for r, e, d in zip(rates, edges, widths))


def intensity(t, rates, breaks):
    return np.asarray(rates)[np.searchsorted(breaks, t)]


def neg_loglik(theta, T, breaks):
    alpha, rates = np.exp(theta[0]), np.exp(theta[1:])
    obs = w[w <= T]
    L = clock(obs, rates, breaks)
    observed = (alpha - 1) * np.log(L) - L - gammaln(alpha) + np.log(intensity(obs, rates, breaks))
    censored = (n_bonds - len(obs)) * np.log(gammaincc(alpha, clock(T, rates, breaks)))
    return -(observed.sum() + censored)


def hessian(f, x, h=1e-4):
    k = len(x)
    H = np.empty((k, k))
    E = h * np.eye(k)
    for i in range(k):
        for j in range(k):
            H[i, j] = (f(x + E[i] + E[j]) - f(x + E[i] - E[j])
                       - f(x - E[i] + E[j]) + f(x - E[i] - E[j])) / (4 * h**2)
    return H


def fit(T, breaks=()):
    breaks = np.asarray(breaks, dtype=float)
    f = lambda theta: neg_loglik(theta, T, breaks)
    res = minimize(f, np.zeros(len(breaks) + 2), method="Nelder-Mead",
                   options={"xatol": 1e-8, "fatol": 1e-8, "maxiter": 20000})
    se = np.sqrt(np.diag(np.linalg.inv(hessian(f, res.x))))
    lo, hi = np.exp(res.x[0] - 1.96 * se[0]), np.exp(res.x[0] + 1.96 * se[0])
    return {"alpha": np.exp(res.x[0]), "alpha 95% CI": f"[{lo:.2f}, {hi:.2f}]",
            "rates": np.exp(res.x[1:]), "breaks": breaks, "loglik": -res.fun}
The opening hours
Corporate bonds trade over the counter, so there is no opening bell, but almost no customer trades happen before 8:00 a.m. Eastern, an hour and a half before the stock market opens. We first fit the model to that window alone, so T = 1.5 and a bond is censored if it has not traded twice by 9:30.
opening = fit(T=1.5)
print(f"alpha = {opening['alpha']:.2f}, 95% CI {opening['alpha 95% CI']}")
print(f"lambda = {opening['rates'][0]:.3f} per hour")
alpha = 1.66, 95% CI [1.51, 1.82]
lambda = 0.074 per hourThe estimate of \alpha is closer to 2, the value implied by Poisson arrivals, than any estimate below, although the confidence interval excludes 2. Before the stock market opens, bond trades arrive roughly the way the Poisson model describes.
The whole day
Extending the window to the close, T = 9, and keeping one rate for the whole day gives a very different shape.
constant = fit(T=9)
print(f"alpha = {constant['alpha']:.2f}, 95% CI {constant['alpha 95% CI']}")
print(f"lambda = {constant['rates'][0]:.3f} per hour")
alpha = 1.30, 95% CI [1.26, 1.33]
lambda = 0.054 per hourFigure 1 compares the fitted distribution function with the empirical one. Since every bond is observed for the same nine hours, the empirical F(t) is simply the fraction of all bonds in the sample whose second trade came by time t.
grid = np.linspace(0, 9, 400)
empirical = np.searchsorted(np.sort(w), grid, side="right") / n_bonds


def plot_fit(model, label):
    fitted = gammainc(model["alpha"], clock(grid, model["rates"], model["breaks"]))
    fig, ax = plt.subplots(figsize=(7, 4.5))
    ax.plot(grid, empirical, color="black", label="Empirical")
    ax.plot(grid, fitted, linestyle="--", label=label)
    ax.set_xticks(range(10), [f"{h}:00" for h in range(8, 13)] + [f"{h}:00" for h in range(1, 6)])
    ax.set_xlabel("Time of day (Eastern)")
    ax.set_ylabel(r"$P(W \leq t)$")
    ax.set_xlim(0, 9)
    ax.set_ylim(0)
    ax.legend(frameon=False)
    plt.tight_layout()
    plt.show()
plot_fit(constant, rf"Gamma, constant rate, $\hat\alpha$ = {constant['alpha']:.2f}")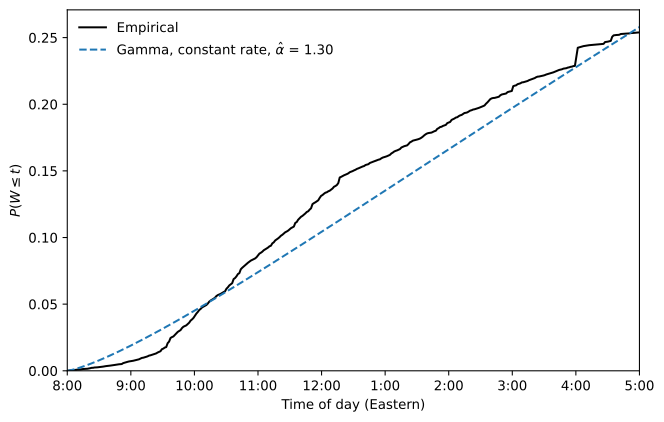
With \hat\alpha = 1.30 the fitted curve rises too early and too slowly. The shape parameter governs how the curve starts, since F(t) \approx (\lambda t)^\alpha / \Gamma(\alpha + 1) for small t. A single rate has to match both the quiet opening and the busy late morning, and lowering \alpha is the only way the model can make the curve rise faster later in the day, at the cost of rising too fast at the start.
A rate that changes at 9:30
The empirical curve bends when the stock market opens. The simplest way to capture this is to let the rate jump at \tau = 1.5, so that the bond market has one rate before 9:30 and another after. With the clock \Lambda(t) in place of \lambda t, the waiting time is still gamma distributed in the sense that \operatorname{P}(W \leq t) = P(\alpha, \Lambda(t)), where P = 1 - Q is the regularized lower incomplete gamma function. The model adds one parameter.
jump = fit(T=9, breaks=[1.5])
print(f"alpha = {jump['alpha']:.2f}, 95% CI {jump['alpha 95% CI']}")
print(f"lambda before 9:30 = {jump['rates'][0]:.4f} per hour")
print(f"lambda after 9:30  = {jump['rates'][1]:.4f} per hour")
print(f"Log-likelihood gain over a constant rate: {jump['loglik'] - constant['loglik']:.1f}")
alpha = 0.79, 95% CI [0.76, 0.81]
lambda before 9:30 = 0.0033 per hour
lambda after 9:30 = 0.0230 per hour
Log-likelihood gain over a constant rate: 440.8plot_fit(jump, rf"Gamma, rate jumps at 9:30, $\hat\alpha$ = {jump['alpha']:.2f}")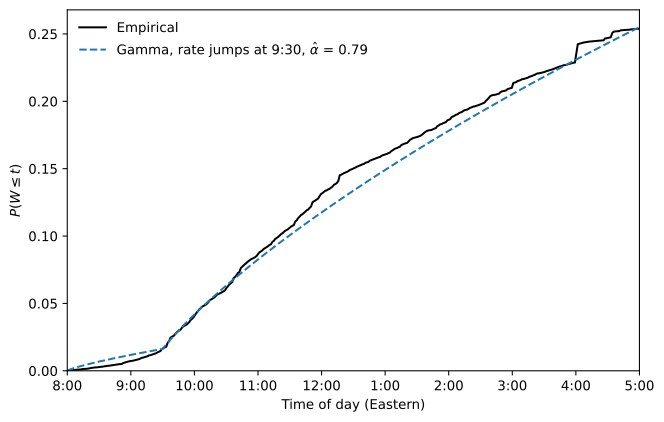
Figure 2 shows that the jump at 9:30 is enough to reproduce the shape of the empirical curve, and the log-likelihood rises by more than 400 for one extra parameter. The rate after the stock market opens is about seven times the rate before it. The levels of the rates cannot be compared with the opening-window estimate, because a different \alpha needs a different clock to produce the same curve; only their ratio is informative. The estimate of \alpha, however, falls below 1, further from 2 than before.
What the estimates say
Table 1 collects the three fits. The log-likelihoods of the two whole-day models can be compared because they use the same data; the opening-window fit uses a shorter window and has no comparable log-likelihood.
models = {
    "Opening hours, 8:00 to 9:30": opening,
    "Whole day, constant rate": constant,
    "Whole day, rate jumps at 9:30": jump,
}
pd.DataFrame(
    {
        "alpha": [f"{m['alpha']:.2f}" for m in models.values()],
        "95% CI": [m["alpha 95% CI"] for m in models.values()],
        "lambda before 9:30": [f"{m['rates'][0]:.4f}" for m in models.values()],
        "lambda after 9:30": [f"{m['rates'][-1]:.4f}" if m is not opening else "" for m in models.values()],
        "Log-likelihood": [f"{m['loglik']:,.1f}" if m is not opening else "" for m in models.values()],
    },
    index=models.keys(),
)| alpha | 95% CI | lambda before 9:30 | lambda after 9:30 | Log-likelihood | |
|---|---|---|---|---|---|
| Opening hours, 8:00 to 9:30 | 1.66 | [1.51, 1.82] | 0.0741 | ||
| Whole day, constant rate | 1.30 | [1.26, 1.33] | 0.0538 | 0.0538 | -35,331.2 |
| Whole day, rate jumps at 9:30 | 0.79 | [0.76, 0.81] | 0.0033 | 0.0230 | -34,890.4 |
Once the intraday pattern is removed, the remaining departure from the Poisson model is a shape parameter below 1. That is what a mixture of slow and fast bonds produces: a mixture of gamma distributions with different rates has more mass at both short and long waits than any single member of the family. The counts point the same way. With a common rate, the number of trades a bond makes during the day would be Poisson, with variance equal to its mean.
print(f"Mean trades per bond: {counts.mean():.2f}")
print(f"Variance:             {counts.var():.2f}")
Mean trades per bond: 2.19
Variance: 194.31The variance is about ninety times the mean: a few bonds trade hundreds of times a day while most never trade. Some of the low \hat\alpha may also come from trades clustering in time within a bond, which the customer-trade filter weakens but does not remove. With one day of data and one rate for all bonds, the two explanations cannot be told apart.
The natural next step is to let the rate depend on bond characteristics, \lambda_i(t) = \lambda(t) \exp(\mathbf{x}_i' \pmb{\beta}), with amount outstanding, age, maturity and rating in \mathbf{x}_i, and to check whether \hat\alpha moves back toward 2 once that heterogeneity is accounted for. Time variation within a bond, beyond the time of day, leads to the autoregressive conditional duration model of Engle and Russell (1998).
Engle, Robert F., and Jeffrey R. Russell. 1998. “Autoregressive Conditional Duration: A New Model for Irregularly Spaced Transaction Data.” Econometrica 66 (5): 1127–62.